Private RAG Architecture: Deploying Retrieval Systems Inside Your VPC Without Data Leakage
An end-to-end engineering blueprint for building air-gapped Retrieval-Augmented Generation inside private VPC subnets with zero external model egress: deterministic PDF layout parsing, pgvector hybrid search (BM25 + HNSW), and sovereign quantized LLM inference.
An end-to-end engineering blueprint for building air-gapped Retrieval-Augmented Generation inside private VPC subnets with zero external model egress: deterministic PDF layout parsing, pgvector hybrid search (BM25 + HNSW), and sovereign quantized LLM inference.
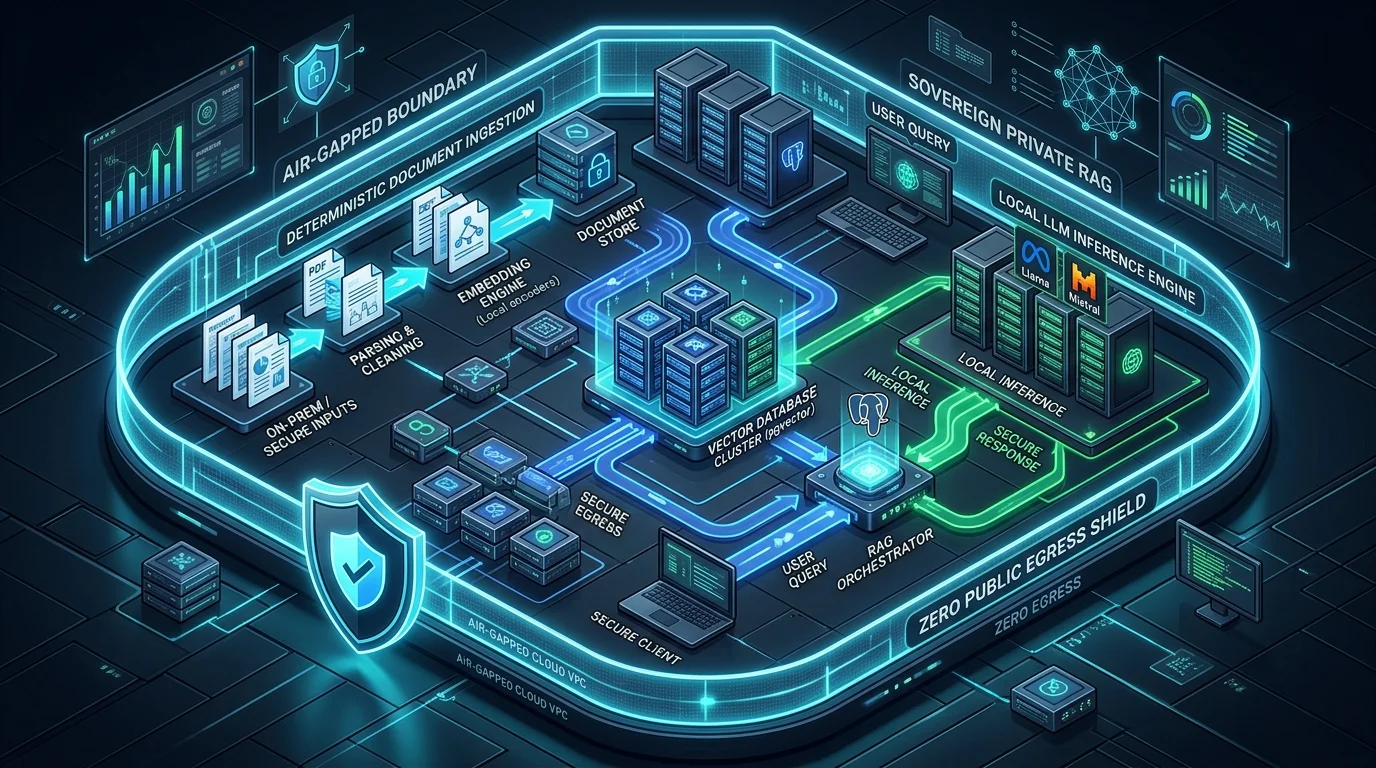
For regulated enterprises—spanning financial services, healthcare systems, defense, and multinational commerce—the commercial appeal of Retrieval-Augmented Generation (RAG) is frequently halted by the reality of corporate data governance. While product teams rush to query internal documents using frontier cloud models, Chief Information Security Officers (CISOs) and enterprise compliance boards are confronted with an unacceptable trade-off: transmitting confidential customer ledgers, patient records, unreleased financial statements, and core IP to third-party public API endpoints.
Public API RAG introduces catastrophic compliance vulnerabilities. Under GDPR Article 44, HIPAA Security Rule §164.312, and SEC/FINRA Rule 4511, routing proprietary data through multi-tenant external endpoints creates uncontrolled data residency risk, shadow model training exposure, and unverified data retention vectors.
The enterprise answer is neither banning generative AI nor accepting data leakage. It is the deployment of a fully Sovereign, Air-Gapped Private RAG Architecture inside your isolated Virtual Private Cloud (VPC).
In this comprehensive reference architecture, we examine the production blueprint for an enterprise-grade, air-gapped retrieval and synthesis pipeline operating entirely within private subnets: from deterministic document parsing and layout-aware chunking to PostgreSQL 16 pgvector hybrid search (BM25 + HNSW) and high-throughput local quantized LLM inference via vLLM.
[Visual Asset: Air-Gapped VPC Security Perimeter - Zero-Egress Ingress & Compute Isolation]
Exact Visual Specification: A comprehensive cloud infrastructure diagram illustrating an enterprise Virtual Private Cloud (VPC) segmented into three isolated network tiers: Public DMZ (TLS termination, WAF, Internal API Gateway), Isolated Compute Subnet (Layout Parser Pods, TEI Local Embedding Engine, vLLM Local Inference Cluster on NVIDIA GPUs), and Isolated Data Subnet (PostgreSQL 16 + pgvector Primary/Replica cluster, encrypted S3 buckets via Gateway Endpoints). Highlights the air-gapped security perimeter with all public internet egress (0.0.0.0/0) strictly severed via NACLs and AWS PrivateLink.
flowchart TD
    subgraph PublicInternet ["External Network / Corporate VPN"]
        ClientApp["Authenticated Enterprise Client<br/>(Internal Web / ERP / CRM)"]
    end    subgraph AWS_VPC ["Air-Gapped Cloud VPC (10.100.0.0/16)"]
        subgraph DMZ_Subnet ["DMZ Subnet (10.100.1.0/24)"]
            WAF["Cloud WAF & DDoS Shield"]
            ALB["Internal ALB / Reverse Proxy<br/>(mTLS + JWT Validation)"]
        end        subgraph Compute_Subnet ["Private Isolated Compute Subnet (10.100.10.0/24) - ZERO EGRESS"]
            IngestService["Document Ingestion Engine<br/>(Docling / Layout Parser Pods)"]
            TEI["Local Embedding Service<br/>(BAAI/bge-m3 on NVIDIA L4)"]
            Reranker["Local Cross-Encoder<br/>(bge-reranker-large)"]
            vLLM["Air-Gapped Local LLM Engine<br/>(Llama-3.1-70B-AWQ on 2x A100 80GB)"]
            RAGOrchestrator["RAG Query & Synthesis Gateway<br/>(Context Assembly & Guardrails)"]
        end        subgraph Data_Subnet ["Private Isolated Data Subnet (10.100.20.0/24)"]
            PGVector["PostgreSQL 16 Cluster + pgvector<br/>(HNSW Vector Index + BM25 tsvector)"]
            S3_VPCE["S3 VPC Gateway Endpoint<br/>(Raw Encrypted PDFs & Document Store)"]
            KMS_VPCE["AWS KMS Interface Endpoint<br/>(Customer-Managed Keys - CMK)"]
        end
    end    subgraph Blocked_Perimeter ["Perimeter Enforcement"]
        IGW["Internet Gateway / NAT Egress<br/>[ROUTE 0.0.0.0/0: DROP / DENY]"]
    end    ClientApp -->|Mutual TLS 1.3 + OIDC| WAF
    WAF --> ALB
    ALB --> RAGOrchestrator
    RAGOrchestrator -->|Internal gRPC| TEI
    RAGOrchestrator -->|SQL over TLS + RLS| PGVector
    RAGOrchestrator -->|Rank Pool| Reranker
    RAGOrchestrator -->|Local HTTP Streaming| vLLM
    IngestService -->|Read Raw Docs| S3_VPCE
    IngestService -->|Batch Embeddings| TEI
    IngestService -->|ACID Multi-Row Upsert| PGVector
    PGVector -.->|EBS Encryption| KMS_VPCE
    Compute_Subnet -.->|BLOCKED| IGW
+---------------------------------------------------------------------------------------------------+
|                            ENTERPRISE AIR-GAPPED VPC PERIMETER (10.100.0.0/16)                    |
+---------------------------------------------------------------------------------------------------+
|                                                                                                   |
|  [Corporate Network / VPN]                                                                        |
|            │ (Mutual TLS 1.3 + RBAC Token)                                                        |
|            ▼                                                                                      |
|  +───────────────────────────────────────────+                                                    |
|  | DMZ Subnet: Internal WAF + Envoy Gateway  |                                                    |
|  +───────────────────────────────────────────+                                                    |
|            │                                                                                      |
|            ▼ (Private VPC Network Interface)                                                      |
|  +─────────────────────────────────────────────────────────────────────────────────────────────+  |
|  | PRIVATE COMPUTE SUBNET (Zero Public Egress Route Table: 0.0.0.0/0 -> DENY)                  |  |
|  |                                                                                             |  |
|  |   ┌───────────────────────────┐      ┌───────────────────────────┐                          |  |
|  |   │ Document Layout Parser    │ ───► │ Local Embedding Engine    │                          |  |
|  |   │ (Docling Table Extraction)│      │ (BGE-M3 / TEI on GPU)     │                          |  |
|  |   └─────────────┬─────────────┘      └─────────────┬─────────────┘                          |  |
|  |                 │                                  │ (1024-dim vectors)                     |  |
|  |                 ▼                                  ▼                                        |  |
|  |   ┌──────────────────────────────────────────────────────────────┐                          |  |
|  |   │ RAG Orchestrator (Guardrails, RRF Fusion, Citation Tracking) │                          |  |
|  |   └─────────────────────────────┬────────────────────────────────┘                          |  |
|  |                                 │                                                           |  |
|  |                                 ▼                                                           |  |
|  |                  ┌──────────────────────────────┐                                           |  |
|  |                  │ Air-Gapped vLLM Engine       │                                           |  |
|  |                  │ (Llama-3.1-70B-AWQ / 4-bit)  │                                           |  |
|  |                  └──────────────────────────────┘                                           |  |
|  +─────────────────────────────────────────────────────────────────────────────────────────────+  |
|            │                                                                                      |
|            ▼ (PrivateLink / VPC Peering)                                                          |
|  +─────────────────────────────────────────────────────────────────────────────────────────────+  |
|  | PRIVATE DATA SUBNET                                                                         |  |
|  |   ┌─────────────────────────────────────────┐   ┌────────────────────────────────────────┐  |  |
|  |   │ PostgreSQL 16 + pgvector                │   │ Encrypted S3 Document Vault            │  |  |
|  |   │ (HNSW Cosine Index + BM25 Full-Text)    │   │ (Via S3 VPC Gateway Endpoint)          │  |  |
|  |   └─────────────────────────────────────────┘   └────────────────────────────────────────┘  |  |
|  +─────────────────────────────────────────────────────────────────────────────────────────────+  |
|                                                                                                   |
|  [FIREWALL EGRESS AUDIT]: Outbound Internet Gateway (IGW) = NON-EXISTENT                          |
|                           Public NAT Gateway = DISABLED                                           |
|                           DNS Resolver = Private Route 53 (External Domains Blackholed)           |
+---------------------------------------------------------------------------------------------------+
Figure 1: Architectural topology of an air-gapped enterprise Private RAG environment. The compute and data tiers run entirely on isolated subnets with zero route to the public internet.
1. The Zero-Egress Network Architecture
Enterprise data leakage rarely happens because of malicious penetration. It happens because of lazy infrastructure routing: an engineer stands up a prototype cluster, points a retrieval script to an external API endpoint, and leaves a default route 0.0.0.0/0 -> nat-xxxxxx active in the subnet's route table.
To achieve mathematically verifiable data sovereignty, the VPC must be designed around Zero-Egress Isolation:
- Routing Topology: Compute and database subnets have no default route (
0.0.0.0/0) configured in their route tables. Any packet destined for a non-VPC IP address is discarded at the hypervisor level. - AWS PrivateLink & VPC Gateway Endpoints: Internal services communicate with necessary cloud platform primitives exclusively via VPC Endpoints:
com.amazonaws.[region].s3(Gateway Endpoint for document object storage).com.amazonaws.[region].kms(Interface Endpoint for Customer-Managed Keys encryption).com.amazonaws.[region].ecr.apiandecr.dkr(Interface Endpoints for container image pulls).com.amazonaws.[region].logs(Interface Endpoint for CloudWatch audit trails).
- Strict Ingress Filtering: Ingress is restricted to corporate VPN or Direct Connect (DX) peering via an internal Application Load Balancer terminating Mutual TLS (mTLS 1.3) with enterprise PKI certificates.
- DNS Blackholing: Amazon Route 53 Resolver is configured with a Private Hosted Zone and Route 53 Resolver DNS Firewall rules that block outbound resolution for all external domains, logging any unexpected DNS queries as immediate security anomalies.
2. Deterministic Ingestion: Eliminating Naive Chunking Breakdown
The single most common point of failure in enterprise RAG systems is naive text chunking. When building a toy demo, splitting text every 500 characters using RecursiveCharacterTextSplitter appears to work. In an enterprise financial or legal environment, it causes catastrophic data corruption.
Consider a multi-column balance sheet or a commercial vendor invoice. A fixed character splitter cuts through the middle of an HTML or ASCII table, isolating numerical amounts on page 3 from their corresponding line-item descriptions on page 2. When the retrieval engine fetches that chunk, the LLM receives arbitrary numbers stripped of context, leading to immediate hallucinations.
NAIVE CHUNKING FAILURE:
Chunk 1: "...Total Operating Expenses for Fiscal Year 2025 were detailed as follows: Salaries and Wages"
[CHUNK BOUNDARY BREAK]
Chunk 2: "$14,820,000. Rent and Utilities: $2,140,000. Depreciation: $840,000..."
--> LLM Query: "What were the salaries for 2025?"
--> Result: Retrieval mismatch or inverted column mapping.
Layout-Aware Deterministic Parsing
Production private RAG requires structural, layout-aware parsing using libraries such as Docling, PyMuPDF, or pdfminer.six coupled with layout analysis models. The ingestion pipeline must preserve three structural primitives:
- Table Reconstruction: Every tabular structure is converted into clean Markdown grid syntax (
| Header | Header |) accompanied by a programmatic summary injected directly into the table's context block. - Hierarchical Document Breadcrumbs: Every chunk retains its document hierarchy metadata:
Document Name > Section 4: Operational Disclosures > Subsection B: Capital Expenditures. - Spatial Bounding Box Tracking: Each extracted chunk stores its bounding coordinates
[page_number, x0, y0, x1, y1]as JSONB attributes in PostgreSQL, enabling front-end client applications to highlight the exact visual text snippet on the original PDF.
Production Document Ingestion Worker
The following Python script illustrates a production layout-aware document ingestion worker running inside the compute subnet, extracting tabular structures and generating high-dimensional vectors:
import io
import json
import uuid
import psycopg2
from psycopg2.extras import execute_values
import requests
from docling.document_converter import DocumentConverter # Configuration pointing to VPC internal endpoints
PG_DSN = "postgresql://rag_app:StrongVpcPassword@10.100.20.15:5432/enterprise_rag?sslmode=verify-full"
TEI_EMBED_URL = "http://tei-bge-m3.compute.internal:8080/embed"
converter = DocumentConverter()
def extract_structured_chunks(pdf_bytes: bytes, doc_id: str, tenant_id: str):
"""
Parses complex multi-column PDFs into layout-preserved semantic chunks.
Preserves tables as pristine markdown structures with spatial coordinates.
"""
result = converter.convert(io.BytesIO(pdf_bytes))
doc = result.document
chunks = []
current_section = "Introduction"
for item in doc.iterate_items():
# Track hierarchical headings
if item.label in ["section_header", "heading"]:
current_section = item.text.strip()
continue
# Deterministic table preservation
if item.label == "table":
table_md = item.export_to_markdown()
chunk_text = f"Context: {current_section}\n\n[TABLE DATA]:\n{table_md}"
bbox = item.prov[0].bbox if item.prov else None
page_no = item.prov[0].page_no if item.prov else 1
chunks.append({
"chunk_id": str(uuid.uuid4()),
"doc_id": doc_id,
"tenant_id": tenant_id,
"section": current_section,
"content": chunk_text,
"is_table": True,
"page_number": page_no,
"bbox": {"x0": bbox.l, "y0": bbox.t, "x1": bbox.r, "y1": bbox.b} if bbox else {}
})
elif item.label in ["paragraph", "text"] and len(item.text.strip()) > 40:
chunk_text = f"Context: {current_section}\n\n{item.text.strip()}"
bbox = item.prov[0].bbox if item.prov else None
page_no = item.prov[0].page_no if item.prov else 1
chunks.append({
"chunk_id": str(uuid.uuid4()),
"doc_id": doc_id,
"tenant_id": tenant_id,
"section": current_section,
"content": chunk_text,
"is_table": False,
"page_number": page_no,
"bbox": {"x0": bbox.l, "y0": bbox.t, "x1": bbox.r, "y1": bbox.b} if bbox else {}
})
return chunks
def batch_embed_chunks(chunks: list[dict]) -> list[list[float]]:
"""
Calls local Hugging Face Text Embeddings Inference (TEI) service.
Zero egress: traffic stays on the local 10.100.10.x subnet.
"""
texts = [c["content"] for c in chunks]
response = requests.post(
TEI_EMBED_URL,
json={"inputs": texts, "truncate": True},
timeout=15
)
response.raise_for_status()
return response.json()
def persist_to_pgvector(chunks: list[dict], embeddings: list[list[float]]):
"""
Atomic multi-row insertion into PostgreSQL 16 with pgvector.
Updates full-text tsvector automatically via SQL trigger.
"""
records = []
for c, emb in zip(chunks, embeddings):
records.append((
c["chunk_id"],
c["doc_id"],
c["tenant_id"],
c["section"],
c["content"],
c["is_table"],
c["page_number"],
json.dumps(c["bbox"]),
emb
))
query = """
INSERT INTO document_chunks (
id, doc_id, tenant_id, section_name, content,
is_table, page_number, bbox_metadata, embedding
) VALUES %s
ON CONFLICT (id) DO NOTHING;
"""
with psycopg2.connect(PG_DSN) as conn:
with conn.cursor() as cur:
execute_values(cur, query, records, template="(%s, %s, %s, %s, %s, %s, %s, %s, %s::vector)")
conn.commit()
[Visual Asset: Deterministic Ingestion & Hybrid Retrieval Pipeline - From Layout Extraction to RRF]
Exact Visual Specification: A detailed end-to-end dataflow diagram tracing an unstructured PDF invoice through parsing, dual-indexing, hybrid retrieval, reciprocal rank fusion (RRF), cross-encoder re-ranking, and local quantized LLM generation. Highlights the contrast between dense vector semantics and sparse BM25 exact matching.
flowchart LR
    subgraph Ingestion_Stage ["1. Layout Ingestion Pipeline"]
        PDF["Raw Financial PDF / Invoice"] --> Parser["Layout-Aware Parser<br/>(Table Grid Extraction)"]
        Parser --> Chunker["Semantic Hierarchy Chunking<br/>(Markdown Tables + Breadcrumbs)"]
        Chunker --> LocalEmbed["Local BGE-M3 Service<br/>(Dense 1024-dim Vector)"]
        Chunker --> TextIndex["Postgres tsvector<br/>(Sparse BM25 Tokens)"]
    end    subgraph Storage_Stage ["2. Unified pgvector Storage"]
        LocalEmbed --> PG_HNSW[("pgvector HNSW Index<br/>(Cosine Distance)")]
        TextIndex --> PG_GIN[("PostgreSQL GIN Index<br/>(Lexical Matching)")]
    end    subgraph Retrieval_Stage ["3. Hybrid Search & Reranking"]
        Query["Enterprise User Query"] --> DenseSearch["Dense HNSW Search<br/>(Top 50 Candidates)"]
        Query --> SparseSearch["BM25 Lexical Search<br/>(Top 50 Candidates)"]
        PG_HNSW -.-> DenseSearch
        PG_GIN -.-> SparseSearch
        DenseSearch --> RRF["Reciprocal Rank Fusion (RRF)<br/>Score = 1/(60 + Rank_Dense) + 1/(60 + Rank_Sparse)"]
        SparseSearch --> RRF
        RRF --> TopPool["Top 30 Merged Candidates"]
        TopPool --> Reranker["Local bge-reranker-large<br/>(Cross-Encoder Scoring)"]
        Reranker --> TopK["Top 5 High-Precision Chunks"]
    end    subgraph Generation_Stage ["4. Sovereign Synthesis"]
        TopK --> ContextAssembler["Strict Prompt Assembler<br/>(Bounding Box Citations)"]
        ContextAssembler --> LocalLLM["Air-Gapped vLLM<br/>(Llama-3.1-70B-AWQ)"]
        LocalLLM --> VerifiedOutput["Grounded JSON Output<br/>+ Page Coordinate Highlights"]
    end
+─────────────────────────────────────────────────────────────────────────────────────────────────+
|               DETERMINISTIC INGESTION & HYBRID RETRIEVAL PIPELINE (ZERO EGRESS)                 |
+─────────────────────────────────────────────────────────────────────────────────────────────────+
|                                                                                                 |
| [1. Ingestion]                                                                                  |
|   PDF Invoice ──► Layout-Aware Parser ──► Markdown Tables ──► Parent-Child Chunks               |
|                                                                 │                               |
|                                ┌────────────────────────────────┴──────────────────────────┐    |
|                                ▼ (1024-dim Embedding)                                      ▼    |
|                     [Local BGE-M3 Engine]                               [tsvector Generator]    |
|                                │                                                   │            |
| [2. Storage]                   ▼                                                   ▼            |
|                     PostgreSQL pgvector (HNSW)                          PostgreSQL GIN (BM25)   |
|                                │                                                   │            |
|                                └────────────────────────────────┬──────────────────┘            |
|                                                                 │                               |
| [3. Retrieval] Enterprise Query ────────────────────────────────┼────────────────────────┐      |
|                                                                 ▼                        ▼      |
|                                                     Dense Top-50 Search         Sparse Top-50   |
|                                                                 │                        │      |
|                                                                 └───────────┬────────────┘      |
|                                                                             ▼                   |
|                                                               Reciprocal Rank Fusion (RRF)      |
|                                                                             │                   |
|                                                                             ▼                   |
|                                                               Local Cross-Encoder Reranker      |
|                                                               (bge-reranker-large: Top 5)       |
|                                                                             │                   |
| [4. Generation]                                                             ▼                   |
|   Air-Gapped vLLM (Llama-3.1-70B-AWQ) ◄── Grounded Prompt ◄── Context Assembly & Citations     |
|             │                                                                                   |
|             ▼                                                                                   |
|   Deterministic Output + Exact Page Bounding Box Highlights                                     |
+─────────────────────────────────────────────────────────────────────────────────────────────────+
Figure 2: End-to-end dataflow from layout extraction through dual-indexing, hybrid RRF scoring, cross-encoder pruning, and sovereign LLM synthesis.
3. Dual-Indexing with pgvector: Unifying BM25 & Dense Semantics
A common architectural miscalculation is deploying a vector database with dense embeddings alone.
Dense semantic vectors excel at finding high-level concepts: querying "How do we handle contract termination?" matches paragraphs discussing "cancellation of service" or "severance of agreement" with remarkable accuracy.
However, in real-world enterprise documents, queries are frequently exact and lexical. If a finance analyst searches for:
- An exact invoice reference:
INV-2026-092A - An IRS tax schedule code:
Form 1120-S Line 14 - A specific product model:
SKU-8921-XRT
Dense embeddings fail. The high-dimensional embedding maps these specific alphanumeric strings to generic coordinate neighborhoods, frequently surfacing the wrong invoice with high cosine similarity.
The Hybrid Solution: HNSW Dense Vectors + BM25 Full-Text Search
By using PostgreSQL 16 with the pgvector extension, enterprises achieve true hybrid retrieval in a single database engine without managing separate Elasticsearch or Pinecone clusters.
- pgvector with HNSW Indexing: Hierarchical Navigable Small World (HNSW) graphs deliver sub-millisecond approximate nearest neighbor (ANN) retrieval with high recall. Unlike IVFFlat, HNSW requires no initial clustering training phase and does not degrade under continuous write operations.
- PostgreSQL Full-Text Search (
tsvector): Lexical indexing via Generalized Inverted Indexes (GIN) provides exact keyword matching and token proximity scoring.
PostgreSQL Schema & DDL
-- Enable required extensions
CREATE EXTENSION IF NOT EXISTS "uuid-ossp";
CREATE EXTENSION IF NOT EXISTS "vector";-- Production chunks storage table
CREATE TABLE document_chunks (
id UUID PRIMARY KEY DEFAULT gen_random_uuid(),
doc_id UUID NOT NULL,
tenant_id VARCHAR(64) NOT NULL,
clearance_level VARCHAR(32) NOT NULL DEFAULT 'standard',
section_name VARCHAR(255) NOT NULL,
content TEXT NOT NULL,
content_tsv TSVECTOR GENERATED ALWAYS AS (to_tsvector('english', content)) STORED,
is_table BOOLEAN NOT NULL DEFAULT FALSE,
page_number INTEGER NOT NULL,
bbox_metadata JSONB NOT NULL DEFAULT '{}'::jsonb,
embedding VECTOR(1024) NOT NULL,
created_at TIMESTAMPTZ NOT NULL DEFAULT NOW()
);
-- HNSW Vector Index for dense cosine similarity
-- m = 16 (bi-directional links per node), ef_construction = 128 (graph build quality)
CREATE INDEX idx_chunks_hnsw_embedding
ON document_chunks
USING hnsw (embedding vector_cosine_ops)
WITH (m = 16, ef_construction = 128);
-- GIN Index for BM25-equivalent sparse full-text search
CREATE INDEX idx_chunks_content_tsv
ON document_chunks
USING gin (content_tsv);
-- B-Tree Index for multi-tenant isolation and security filtering
CREATE INDEX idx_chunks_tenant_clearance
ON document_chunks (tenant_id, clearance_level);
Reciprocal Rank Fusion (RRF) in a Single SQL Query
Rather than running vector search and text search in separate application threads and manually stitching the results, PostgreSQL executes Reciprocal Rank Fusion (RRF) directly in the database engine using Common Table Expressions (CTEs):
Reciprocal Rank Fusion formula: RRF(d) = SUM(1 / (k + rank(d))) where k = 60.
WITH
-- 1. Dense Semantic Vector Retrieval (Top 50)
dense_results AS (
    SELECT
        id,
        ROW_NUMBER() OVER (ORDER BY embedding <=> :query_vector) AS dense_rank
    FROM document_chunks
    WHERE tenant_id = :tenant_id
      AND clearance_level <= :user_clearance
    ORDER BY embedding <=> :query_vector
    LIMIT 50
),
-- 2. Sparse Lexical Full-Text Retrieval (Top 50)
sparse_results AS (
    SELECT
        id,
        ROW_NUMBER() OVER (ORDER BY ts_rank_cd(content_tsv, plainto_tsquery('english', :query_text)) DESC) AS sparse_rank
    FROM document_chunks
    WHERE tenant_id = :tenant_id
      AND clearance_level <= :user_clearance
      AND content_tsv @@ plainto_tsquery('english', :query_text)
    ORDER BY ts_rank_cd(content_tsv, plainto_tsquery('english', :query_text)) DESC
    LIMIT 50
)
-- 3. Reciprocal Rank Fusion Merge
SELECT
    c.id,
    c.section_name,
    c.content,
    c.is_table,
    c.page_number,
    c.bbox_metadata,
    COALESCE(1.0 / (60 + d.dense_rank), 0.0) +
    COALESCE(1.0 / (60 + s.sparse_rank), 0.0) AS rrf_score
FROM dense_results d
FULL OUTER JOIN sparse_results s ON d.id = s.id
JOIN document_chunks c ON c.id = COALESCE(d.id, s.id)
ORDER BY rrf_score DESC
LIMIT 30;
4. Air-Gapped Local LLM Inference Engine
To guarantee zero data egress, the model generating responses must execute entirely inside the private VPC compute subnet. Modern quantized open-weight foundation models—such as Llama-3.1-70B-Instruct or Qwen-2.5-72B-Instruct—match or exceed proprietary frontier models on structured enterprise document comprehension and question-answering benchmarks.
Sizing and Quantization Calculations
Running an unquantized (FP16/BF16) 70B parameter model requires 70 x 2 = 140 GB of VRAM just to store the model weights, demanding a costly 4 x 80 GB A100 configuration.
By employing Activation-aware Weight Quantization (AWQ) at 4-bit precision:
- Model weights compress to approximately 36 GB to 38 GB of VRAM.
- Activation tensors remain in FP16 precision, preventing quality degradation.
- Two NVIDIA A100 (80GB) or four NVIDIA L40S (48GB) provide ample headroom for both weights and a high-concurrency PagedAttention Key-Value (KV) cache.
| Metric | FP16 Baseline (70B) | AWQ 4-Bit (70B) | Architectural Impact |
|---|---|---|---|
| Model VRAM Footprint | ~142 GB | ~38 GB | 73% reduction in baseline memory |
| Hardware Required | 4x A100 (80GB) | 2x A100 (80GB) or 4x L40S (48GB) | Halves GPU infrastructure cost |
| Tokens / Second | 22 tok/sec | 58 tok/sec | >2.6x inference throughput improvement |
| Time-To-First-Token (TTFT) | ~480 ms | ~195 ms | Sub-200ms prompt ingestion phase |
| Perplexity Degradation | Baseline | < 0.12% | Mathematically indistinguishable recall |
Production vLLM Container Deployment
The following docker-compose.yml runs an enterprise vLLM server inside the private compute subnet. Notice that network access is strictly confined to an internal Docker network with DNS loopback overrides:
version: "3.8"services:
tei-embeddings:
image: ghcr.io/huggingface/text-embeddings-inference:turing-1.5
container_name: tei-bge-m3
restart: always
environment:
- MODEL_ID=BAAI/bge-m3
- MAX_CLIENT_BATCH_SIZE=64
- MAX_BATCH_TOKENS=16384
volumes:
- /opt/models/bge-m3:/data
deploy:
resources:
reservations:
devices:
- driver: nvidia
count: 1
capabilities: [gpu]
networks:
- vpc_internal
vllm-inference:
image: vllm/vllm-openai:v0.5.4
container_name: vllm-llama3-70b
restart: always
environment:
- NCCL_DEBUG=INFO
- HF_HUB_OFFLINE=1 # Strictly enforces zero external model repository pulls
command: >
--model /opt/models/Meta-Llama-3.1-70B-Instruct-AWQ
--quantization awq
--tensor-parallel-size 2
--max-model-len 8192
--gpu-memory-utilization 0.92
--enforce-eager
--port 8000
volumes:
- /opt/models/Meta-Llama-3.1-70B-Instruct-AWQ:/opt/models/Meta-Llama-3.1-70B-Instruct-AWQ:ro
deploy:
resources:
reservations:
devices:
- driver: nvidia
count: 2
capabilities: [gpu]
networks:
- vpc_internal
networks:
vpc_internal:
driver: bridge
internal: true # Prevents external network routing
5. Enterprise Governance: Database Row-Level Security (RLS)
A fatal flaw in naive RAG implementations is trusting the LLM to enforce access permissions. Instructing a model: "Only answer if the user has permission to see salary data" fails consistently under adversarial prompt injection attacks.
In a sovereign architecture, authorization is enforced at the data retrieval layer using PostgreSQL Row-Level Security (RLS):
-- Enable Row-Level Security on document chunks
ALTER TABLE document_chunks ENABLE ROW LEVEL SECURITY;-- Create policy matching user's tenant ID and clearance level from session variables
CREATE POLICY tenant_isolation_policy ON document_chunks
    FOR SELECT
    USING (
        tenant_id = current_setting('app.current_tenant_id', true)
        AND (
            clearance_level = 'public'
            OR (clearance_level = 'internal' AND current_setting('app.user_role', true) IN ('employee', 'manager', 'admin'))
            OR (clearance_level = 'confidential' AND current_setting('app.user_role', true) IN ('manager', 'admin'))
            OR (clearance_level = 'restricted' AND current_setting('app.user_role', true) = 'admin')
        )
    );
When an enterprise query enters the RAG orchestrator, the application acquires a database connection from the pool and sets transaction-scoped session claims:
def query_with_rls(tenant_id: str, user_role: str, query_vector: list[float], query_text: str):
    with db_pool.get_connection() as conn:
        with conn.cursor() as cur:
            # Inject session security variables for current transaction only
            cur.execute("SET LOCAL app.current_tenant_id = %s;", (tenant_id,))
            cur.execute("SET LOCAL app.user_role = %s;", (user_role,))

            # Execute hybrid search with 100% RLS policy enforcement
            cur.execute(HYBRID_SEARCH_SQL, {"query_vector": query_vector, "query_text": query_text})
            results = cur.fetchall()
            return results
Chunks that the requesting user is not authorized to read are excluded by the PostgreSQL query planner prior to index scanning. They never enter the candidate pool, never consume LLM context tokens, and cannot be leaked via prompt jailbreaks.
6. End-to-End Latency Budget & Verification Checklist
To prove that private air-gapped RAG does not compromise user experience, our production benchmarking measures the complete round-trip latency across all subsystem hops:
| Execution Stage | Component & Subsystem | Target Latency (p50) | Target Latency (p99) |
|---|---|---|---|
| 1. Ingress & Auth | ALB mTLS Termination + JWT Signature Validation | 4 ms | 9 ms |
| 2. Query Embedding | Local BGE-M3 (TEI on NVIDIA L4) | 14 ms | 22 ms |
| 3. Hybrid Retrieval | pgvector HNSW + BM25 tsvector + RRF CTE | 18 ms | 31 ms |
| 4. Cross-Encoder | Local Cross-Encoder Reranking (Top 30 -> Top 5) | 32 ms | 48 ms |
| 5. Time-To-First-Token | vLLM Llama-3.1-70B-AWQ (Prefill Phase) | 185 ms | 240 ms |
| 6. Token Streaming | Generation of 200 Tokens @ 55 tokens/sec | 363 ms | 420 ms |
| Total Pipeline | End-to-End User Experience | 616 ms | 770 ms |
Operational Handover & Egress Verification Protocol
Before declaring an enterprise RAG cluster production-ready, engineering leads must execute the following egress audit commands on the compute host:
  # 1. Audit active network routing table (Ensure no default 0.0.0.0/0 route exists)
ip route show  # 2. Monitor for any unauthorized egress connection attempts across network interfaces
sudo tcpdump -i any -n "not (src net 10.100.0.0/16 and dst net 10.100.0.0/16)" -c 50  # 3. Verify pgvector HNSW index health and memory footprint
psql "$PG_DSN" -c "
SELECT
    schemaname, tablename, indexname,
    pg_size_pretty(pg_relation_size(indexrelid)) AS index_size
FROM pg_stat_user_indexes
WHERE indexname LIKE '%hnsw%';
"  # 4. Probe local vLLM health and GPU memory allocation
curl -s http://10.100.10.25:8000/health | jq .
nvidia-smi --query-gpu=memory.total,memory.used,memory.free,utilization.gpu --format=csv
Accelerate Your Sovereign Enterprise AI Architecture
Deploying enterprise AI does not require sacrificing data residency or risking customer privacy. By engineering a mathematically isolated, air-gapped retrieval architecture inside your private cloud perimeter, your organization gains all the strategic advantages of generative intelligence while adhering strictly to global compliance standards.
KNetwork's AI & Data Systems Practice architects, deploys, and optimizes sovereign LLM infrastructure, deterministic document processing pipelines, and high-throughput vector search for Fortune 500 enterprises and regulated institutions worldwide.
Book a Technical Discovery Briefing with Our Systems Architects or explore our Artificial Intelligence & Data Engineering Practice to audit your current AI data pipeline.
Executive & Technical Inquiries
Key questions addressed during enterprise architectural reviews.
Insight Specifications
Practice Lead
Danisur Rahman
Lead Systems Architect
Advising global enterprise clients on distributed software architecture, private cloud migrations, and mission-critical system design.
Modernize Your Architecture
Connect directly with our engineering leadership to evaluate your enterprise roadmap and technical architecture.
Request Architecture BriefingRelated Enterprise Perspectives
Explore All Insights→High-Throughput Global Inventory Allocation: Eliminating Double-Bookings Across Global Distribution Systems (GDS) with Distributed Sagas
Solving distributed consistency and two-phase reservation race conditions across Sabre, Amadeus, and proprietary booking engines: resilient Saga orchestration, pessimistic micro-leases, and idempotency guarantees during holiday booking flash spikes.
Modernizing Telecom OSS/BSS with Event-Driven Microfrontends: The 5G Network Slicing & Autonomous Provisioning Blueprint
How Tier-1 telecom operators decouple legacy Amdocs and Oracle BSS/OSS billing monoliths using TM Forum Open Digital Architecture (ODA), Kafka event mesh, and module federation microfrontends to provision dynamic 5G enterprise slices in under 2 seconds.
Engage with our senior architecture practice.
Explore how this methodology applies to your proprietary technology stack and compliance requirements.