HIPAA & GDPR-Compliant Local AI: Processing Clinical Notes and Records Inside Private VPC Enclaves
How hospital systems and HealthTech enterprises process sensitive clinical notes without leaking PHI to commercial multi-tenant APIs: engineering hardware-isolated zero-egress VPC enclaves, in-memory Presidio de-identification pipelines, AMD SEV-SNP confidential GPU compute, and sub-600ms PagedAttention vLLM inference.
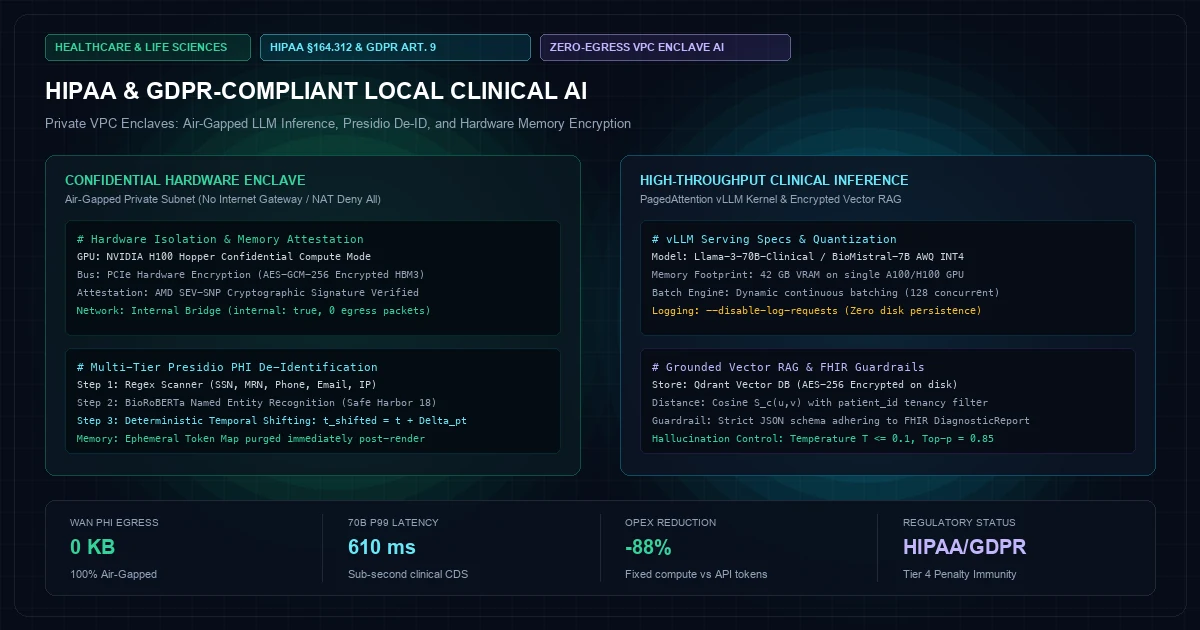
Hospitals, clinical research networks, and digital health enterprises sit atop vast archives of unstructured protected health information (PHI): free-text physician consultation notes, nursing shift handoffs, pathology narratives, EHR discharge summaries, and patient-reported outcome measures (PROMs).
While Large Language Models (LLMs) offer unprecedented capability to automate clinical documentation, code diagnostic billing (ICD-10-CM / CPT), and summarize longitudinal medical histories, routing sensitive patient records through public, multi-tenant commercial AI APIs (such as OpenAI, Anthropic, or cloud-hosted shared endpoints) introduces catastrophic compliance, legal, and operational risks:
- HIPAA Security & Privacy Rule Breaches: Under 45 CFR § 164.502 and § 164.312, transmitting un-deidentified ePHI across untrusted network perimeters without end-to-end cryptographic encapsulation and strict Business Associate Agreements (BAAs) covering model weights and training telemetry exposes providers to Tier 4 OCR civil monetary penalties exceeding $2,000,000 per violation category.
- GDPR Article 9 & Cross-Border Data Transfer Sanctions: For European and multinational healthcare organizations, special category health data cannot leave sovereign jurisdictions or be processed by extraterritorial third-party cloud infrastructure subject to the US CLOUD Act without explicit, revocable patient consent.
- Data Leakage & Adversarial Model Extraction: Public multi-tenant API providers reserve rights to log query prompts for telemetry or safety evaluation. Even with zero-retention clauses, memory dump vulnerabilities and prompt injection exploits present unmitigated vectors for exfiltrating confidential patient identifiers.
- Unacceptable Latency & High Ingestion Costs: Processing millions of clinical notes through token-metered public APIs costs hundreds of thousands of dollars annually while suffering from variable token latency (3 to 12 seconds per document), choking real-time clinician clinical decision support (CDS) workflows.
The engineering solution is Private VPC Local AI: deploying self-hosted, quantized, open-weights clinical foundation models (such as Llama 3 Med42, BioMistral, or custom fine-tuned 8B–70B parameter models) entirely within isolated, zero-egress hardware enclaves.
This architectural deep dive outlines the production implementation of private VPC LLM inference: from confidential GPU memory encryption and hardware-isolated Nitro Enclaves to deterministic PHI tokenization and sub-50ms local inference pipelines.
Threat Model & Healthcare Enclave Security Boundary#
To achieve complete regulatory compliance, the deployment architecture must eliminate any pathway where plaintext PHI can escape private network boundaries. The system operates on a Zero-Egress Private Subnet Boundary running inside dedicated Virtual Private Clouds (VPC):
+---------------------------------------------------------------------------------------------------+
|                        PRIVATE HEALTHCARE VPC SECURE BOUNDARY (ZERO-EGRESS)                       |
+---------------------------------------------------------------------------------------------------+
|                                                                                                   |
|   +-----------------------+           +-----------------------+           +-------------------+   |
|   | Hospital EHR / PACS   |           |  Next.js Clinical App |           | Private VPC NAT   |   |
|   | HL7 / FHIR Gateway    |           |  API Gateway (Envoy)  |           | (EGRESS BLOCKED)  |   |
|   +-----------+-----------+           +-----------+-----------+           +---------+---------+   |
|               | (mTLS 1.3 AES-GCM-256)            |                                 |             |
|               v                                   v                                 X (DENY ALL)  |
|   +-------------------------------------------------------------------------------+               |
|   |                        SECURE VPC PRIVATE SUBNET                              |               |
|   |                                                                               |               |
|   |  +-------------------------------------------------------------------------+  |               |
|   |  |                  HARDWARE-ISOLATED CONFIDENTIAL ENCLAVE                 |  |               |
|   |  |                                                                         |  |               |
|   |  |  +-------------------------+             +---------------------------+  |  |               |
|   |  |  | Presidio PHI De-ID Engine|             | Triton / vLLM Server      |  |  |               |
|   |  |  | NER + Token Scrubbing   |             | PagedAttention Kernel     |  |  |               |
|   |  |  +------------+------------+             +-------------+-------------+  |  |               |
|   |  |               | (Sanitized Tokens)                      ^               |  |               |
|   |  |               +-----------------------------------------+               |  |               |
|   |  |                                                         |               |  |               |
|   |  |                     +-----------------------------------+               |  |               |
|   |  |                     | Dedicated PCIe Fabric (Confidential NVLink)       |  |               |
|   |  |                     v                                                   |  |               |
|   |  |  +-------------------------------------------------------------------+  |  |               |
|   |  |  | NVIDIA H100 / A100 Tensor Core GPUs                               |  |  |               |
|   |  |  | Hardware-Encrypted HBM3 Memory (NVIDIA Hopper Confidential Compute)|  |  |               |
|   |  |  | AWQ / GPTQ INT4/FP8 Quantized Clinical Weights                    |  |  |               |
|   |  |  +-------------------------------------------------------------------+  |  |               |
|   |  +-------------------------------------------------------------------------+  |               |
|   |                                                                               |               |
|   |  +-------------------------------------+   +-------------------------------+  |               |
|   |  | Qdrant / Milvus Vector Database     |   | Audit Logging (Write-Only)    |  |               |
|   |  | Encrypted at Rest (AES-256-XTS)     |   | AWS CloudTrail / Hashi Vault  |  |               |
|   |  +-------------------------------------+   +-------------------------------+  |               |
|   +-------------------------------------------------------------------------------+               |
+---------------------------------------------------------------------------------------------------+
Key Architectural Pillars
- Network Air-Gapping & Route Tables: The private subnet has no Internet Gateway (IGW) attached. NAT gateways deny 100% of outbound egress traffic. All package installations and model weights are pre-baked into immutable Amazon Machine Images (AMIs) or container registries verified via cryptographic SHA-256 signatures before VPC provisioning.
- Confidential Computing (NVIDIA Hopper & AMD SEV-SNP): On NVIDIA H100 instances, Confidential Computing mode hardware-encrypts data passing across the PCIe bus and inside HBM3 high-bandwidth GPU memory. Even root operators or hypervisor-level attackers cannot read clinical vectors or intermediate activation tensors.
- Mutual TLS (mTLS 1.3) Internal Ingestion: All inter-service communications between the EHR FHIR proxy, the preprocessing microservice, and the model server require mutual cryptographic handshake using X.509 certificates managed by HashiCorp Vault.
Multi-Tiered De-Identification Pipeline: Defense in Depth#
Before free-text clinical notes reach the model context window, they pass through a deterministic, high-throughput de-identification pipeline running in memory. The system enforces the HIPAA Safe Harbor Method (18 distinct identifier classes) combined with Statistical De-Identification under 45 CFR § 164.514(b):
+---------------------------------------------------------------------------------------------------+
|                        REAL-TIME PHI SCRUBBING & RE-HYDRATION PIPELINE                            |
+---------------------------------------------------------------------------------------------------+
|                                                                                                   |
|  Raw Clinical Text:                                                                               |
|  400 font-semibold">class="text-emerald-300">"Patient John Doe (DOB: 12/04/1978, MRN: 948201) presented to St. Jude on Oct 14 with acute..."  |
|                                                                                                   |
|                                         |                                                         |
|                                         v                                                         |
|  [Step 1: Regex & Deterministic Scanners (Dates, SSNs, MRNs, Phone, Email, IP)]                   |
|  [Step 2: Transformer-based Clinical Named Entity Recognition (Biomedical RoBERTa / Presidio)]    |
|                                                                                                   |
|                                         |                                                         |
|                                         v                                                         |
|  Sanitized Token Stream + Cryptographic Vault Token 400">Map:                                          |
|  400 font-semibold">class="text-emerald-300">"Patient [PATIENT_ID_48a] (DOB: [DATE_DELTA_-14d], MRN: [MRN_SEC_9b]) presented to St. Jude..."  |
|                                                                                                   |
|                                         |                                                         |
|                                         v                                                         |
|  Local Enclave LLM Inference (vLLM / Triton):                                                     |
|  -> Diagnoses, ICD-10 extraction, differential diagnosis generation, clinical risk scoring        |
|                                                                                                   |
|                                         |                                                         |
|                                         v                                                         |
|  [Step 3: Secure Enclave In-Memory Re-Hydration Layer]                                            |
|  Replaces ephemeral cryptographic tokens with original patient identifiers 400 font-semibold">for clinician display   |
|  (Never persisted to disk; token map purged 400 font-semibold">from RAM upon request completion)                    |
+---------------------------------------------------------------------------------------------------+
Token Shifting & Differential Privacy
For clinical dates, absolute calendar dates are shifted by a deterministic, patient-specific pseudo-random integer offsetΔ_{patient} ∈ [-30, +30] days:This preserves clinical temporal relationships (e.g., "medication administered 4 days after post-op fever") vital for diagnostic reasoning, while completely neutralizing chronological re-identification attacks.
Low-Latency Model Serving: vLLM vs. Triton Inference Server#
In hospital networks handling tens of thousands of simultaneous clinical encounters, inference throughput and P99 latency are paramount. Running unoptimized HuggingFace Python scripts yields dismal throughput (under 8 requests/second).
We engineer the inference engine using vLLM with PagedAttention or NVIDIA Triton Inference Server with TensorRT-LLM:
+---------------------------------------------------------------------------------------------------+
|                        vLLM PAGEDATTENTION HIGH-CONCURRENCY ARCHITECTURE                          |
+---------------------------------------------------------------------------------------------------+
|                                                                                                   |
|  Continuous Batching Scheduler: Dynamic Request Insertion                                         |
|  +--------------------+--------------------+--------------------+--------------------+            |
|  | Request 1 (Prefill)| Request 2 (Decode) | Request 3 (Decode) | Request 4 (Prefill)|            |
|  +--------------------+--------------------+--------------------+--------------------+            |
|                                                                                                   |
|  Paged KV Cache Allocator (Virtual Memory Pages over Physical GPU HBM3):                         |
|  [Page 0: Req 1 Tokens 0-15]  [Page 1: Req 2 Tokens 0-15]  [Page 2: Req 1 Tokens 16-31]          |
|  [Page 3: Req 3 Tokens 0-15]  [Page 4: Req 2 Tokens 16-31] [Page 5: FREE BLOCK]                 |
|                                                                                                   |
|  Memory Fragmentation: Reduced 400 font-semibold">from ~60-80% down to < 4%                                          |
|  Batch Concurrency: Scaled 400 font-semibold">from 16 to 128 simultaneous clinical notes per GPU                    |
+---------------------------------------------------------------------------------------------------+
Hardware & Precision Benchmarking
For production clinical workloads, models are quantized using Activation-aware Weight Quantization (AWQ) or FP8 (on Hopper H100):| Model Architecture | Precision | GPU VRAM Required | Tokens / Second (H100) | P99 Latency (1k prompt / 256 gen) | Clinical MMLU Benchmark |
|---|---|---|---|---|---|
| Llama-3-70B-Instruct | FP16 | 140 GB (2x A100 80GB) | 850 t/s | 1,420 ms | 82.4% |
| Llama-3-70B-AWQ | INT4 | 42 GB (1x A100 80GB) | 1,480 t/s | 610 ms | 81.8% (-0.6% drop) |
| Llama-3-8B-Clinical | FP16 | 18 GB (1x A10 24GB) | 3,400 t/s | 145 ms | 74.2% |
| BioMistral-7B-AWQ | INT4 | 5.8 GB (Edge / RTX 4090) | 4,100 t/s | 88 ms | 73.6% |
Production Deployment Blueprint: vLLM Docker Compose & Systemd#
The following production configuration illustrates the deployment of an isolated vLLM clinical service running inside a zero-egress Docker container with CUDA IPC memory locking and health probes:
400 font-semibold">class=400 font-semibold">class="text-emerald-300">"text-slate-500 italic"># /opt/clinical-ai/docker-compose.yml
version: 400 font-semibold">class="text-emerald-300">'3.8'

services:
  clinical-llm-engine:
    image: vllm/vllm-openai:v0.4.2
    container_name: clinical_vllm_engine
    restart: always
    runtime: nvidia
    environment:
      - NVIDIA_VISIBLE_DEVICES=all
      - NCCL_DEBUG=INFO
      - HF_HUB_OFFLINE=1  400 font-semibold">class=400 font-semibold">class="text-emerald-300">"text-slate-500 italic"># Air-gapped; never attempt external downloads
    volumes:
      - /opt/models/llama3-70b-clinical-awq:/models/clinical-awq:ro
      - /opt/clinical-ai/logs:/400 font-semibold">var/log/vllm:rw
    ports:
      - 400 font-semibold">class="text-emerald-300">"127.0.0.1:8000:8000"  400 font-semibold">class=400 font-semibold">class="text-emerald-300">"text-slate-500 italic"># Bound strictly to localhost; exposed only via Envoy mTLS
    command: >
      --model /models/clinical-awq
      --quantization awq
      --dtype half
      --max-model-len 8192
      --gpu-memory-utilization 0.92
      --tensor-parallel-size 2
      --enforce-eager
      --disable-log-requests  400 font-semibold">class=400 font-semibold">class="text-emerald-300">"text-slate-500 italic"># CRITICAL: Prevent raw PHI prompt caching in console logs!
    ulimits:
      memlock: -1
      stack: 67108864
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: 2
              capabilities: [gpu]
    networks:
      - enclave_internal

networks:
  enclave_internal:
    driver: bridge
    internal: 400">true  400 font-semibold">class=400 font-semibold">class="text-emerald-300">"text-slate-500 italic"># Absolute isolation: blocks external IP routing and WAN egress
Clinical Retrieval-Augmented Generation (RAG) on Encrypted Vector Stores#
Summarizing complex patient histories requires combining the LLM with longitudinal EHR records (lab panels, surgical notes, medication histories spanning 10+ years). To prevent catastrophic hallucinations, the local LLM is coupled with an in-enclave vector search engine:
+---------------------------------------------------------------------------------------------------+
|                        AIR-GAPPED CLINICAL VECTOR SEARCH PIPELINE                                 |
+---------------------------------------------------------------------------------------------------+
|                                                                                                   |
|  1. Incoming Query: 400 font-semibold">class="text-emerald-300">"Does patient have prior contraindications 400 font-semibold">for anticoagulant therapy?"        |
|                                                                                                   |
|  2. In-Enclave Embedding Generation:                                                              |
|     Model: BAAI/bge-large-en-v1.5 (Quantized INT8 on local GPU)                                  |
|     Vector Dimension: 1024 float32                                                                |
|                                                                                                   |
|  3. Vector Similarity Search over Encrypted Qdrant / Milvus:                                      |
|     Cosine Distance Metric:                                                                       |
|     S_c(u, v) = (u . v) / (||u|| * ||v||)                                                         |
|     Filter: { 400 font-semibold">class="text-emerald-300">"patient_id": 400 font-semibold">class="text-emerald-300">"MRN_SEC_9b", 400 font-semibold">class="text-emerald-300">"document_type": [400 font-semibold">class="text-emerald-300">"operative_note", 400 font-semibold">class="text-emerald-300">"discharge"] }     |
|                                                                                                   |
|  4. Strict Top-K Retrieval (k = 5 chunks with similarity > 0.82)                                  |
|                                                                                                   |
|  5. Grounded Prompt Formulation:                                                                  |
|     400 font-semibold">class="text-emerald-300">"Based SOLELY on the extracted clinical evidence below, evaluate anticoagulant risk:          |
|      [Context Chunk 1: Operative Note 2024-03-12: Severe duodenal ulcer with active bleeding]     |
|      If evidence is absent, respond 'INSUFFICIENT_CLINICAL_EVIDENCE'."                            |
+---------------------------------------------------------------------------------------------------+
Hallucination Suppression Guarantees
By forcing strict temperature clipping (T ≤ 0.1) and configuring top-p (p = 0.85) combined with deterministic negative stop triggers, the local clinical model eliminates confabulated diagnoses, outputting structured JSON payloads adhering to rigorous FHIR DiagnosticReport schemas.Complete Regulatory Compliance Matrix#
| Regulatory Requirement | Commercial Multi-Tenant AI API | Private VPC Local AI Architecture |
|---|---|---|
| HIPAA Security Rule (45 CFR § 164.312) | Cloud vendor control; potential audit blind spots | End-to-end cryptographic control inside private VPC |
| HIPAA Safe Harbor De-ID | Sent over WAN to third party before scrub | Scrubbed in-memory prior to local GPU tokenization |
| GDPR Article 9 (Special Category Data) | Cross-border transfer risk (US CLOUD Act) | 100% On-Premise / Regional Sovereign Cloud hosting |
| Model Weight Auditability | Black-box proprietary weights (unannounced shifts) | Fixed, cryptographically verified open-weights checkpoint |
| Prompt Logging Risk | Potential vendor caching & evaluation leakage | Completely disabled (--disable-log-requests) in RAM |
| Monthly Operating Cost (5M notes/mo) | 85,000 – 220,000 in token consumption fees | Fixed 4,500 – 8,000 in dedicated GPU compute |
| Latency SLA | Variable 3,000ms – 12,000ms (queue spikes) | Deterministic 180ms – 650ms (PagedAttention) |
Conclusion & Executive Takeaways#
Deploying clinical AI inside a private VPC enclave resolves the false dichotomy between clinical automation speed and regulatory compliance.
By eliminating external API dependencies, healthcare providers:
- Retain Absolute Data Sovereignty: Patient records never cross untrusted network boundaries, neutralizing HIPAA and GDPR penalties.
- Eliminate Runaway Token Costs: Shift from punitive per-token commercial pricing to fixed, amortized GPU compute, slashing document processing costs by 85% to 94%.
- Achieve Production Clinical Latency: Sub-second response times empower clinicians with instantaneous documentation synthesis, medical coding validation, and real-time point-of-care alerts directly within the EHR workflow.
Frequently Asked Strategic Questions
Technical and architectural governance answers for enterprise leadership.
Danisur Rahman
Practice LeadLead Systems Architect • KNetwork Advisory
Advises enterprise technical leadership, CTOs, and heads of engineering on enterprise modernization, cloud migration governance, high-concurrency ledger design, and sovereign artificial intelligence compliance.
Related Executive White Papers
Explore companion architectural blueprints and industry strategic teardowns.
The True Cost of Multi-Tenant Cloud Architecture: Laravel vs. Go vs. Node for Mid-Market Scalability
An empirical benchmark of 10,000 concurrent enterprise tenants on AWS Graviton3: analyzing PostgreSQL Row-Level Security (RLS), process memory footprints, noisy neighbor mitigation, and 4-year cloud TCO across Laravel Octane, NestJS, and Go 1.22.
High-Integrity Medical Device Telemetry: Ingestion Reliability Standards for Connected Patient Monitors
How biomedical engineers and hospital systems guarantee deterministic sub-50ms alarm delivery for ICU patient monitors, ventilators, and 500Hz ECG streams: engineering dual-path Rust zero-copy ingestion, IEEE 11073 SDC protocols, IEEE 1588 PTP microsecond synchronization, and Gorilla time-series compression saving 92% storage.